Classical vs. Feature-Based Molecular Networking
You can’t wait to start your first molecular network (don’t worry, I understand the feeling). You log in, MS/MS data in hand, ready to explore some chemistry.
But wait..there’s more?
As it turns out, there are two main methods used to perform molecular networking: classical molecular networking (CMN) and feature-based molecular networking (FBMN). The difference between these two begins before you even start building the network and has to do with a mass spectrometry term called feature finding.
Let’s start by looking at mass spectra from two samples. You’ll notice several peaks here, some of which are shared between samples and some of which are unique. If we created a node for each of these peaks, our molecular network would be massive and wouldn’t provide any information on which metabolites are found in multiple samples. So, in classical networking, we use MS2 information to identify the same metabolite in different samples and cluster them into a single representative node.
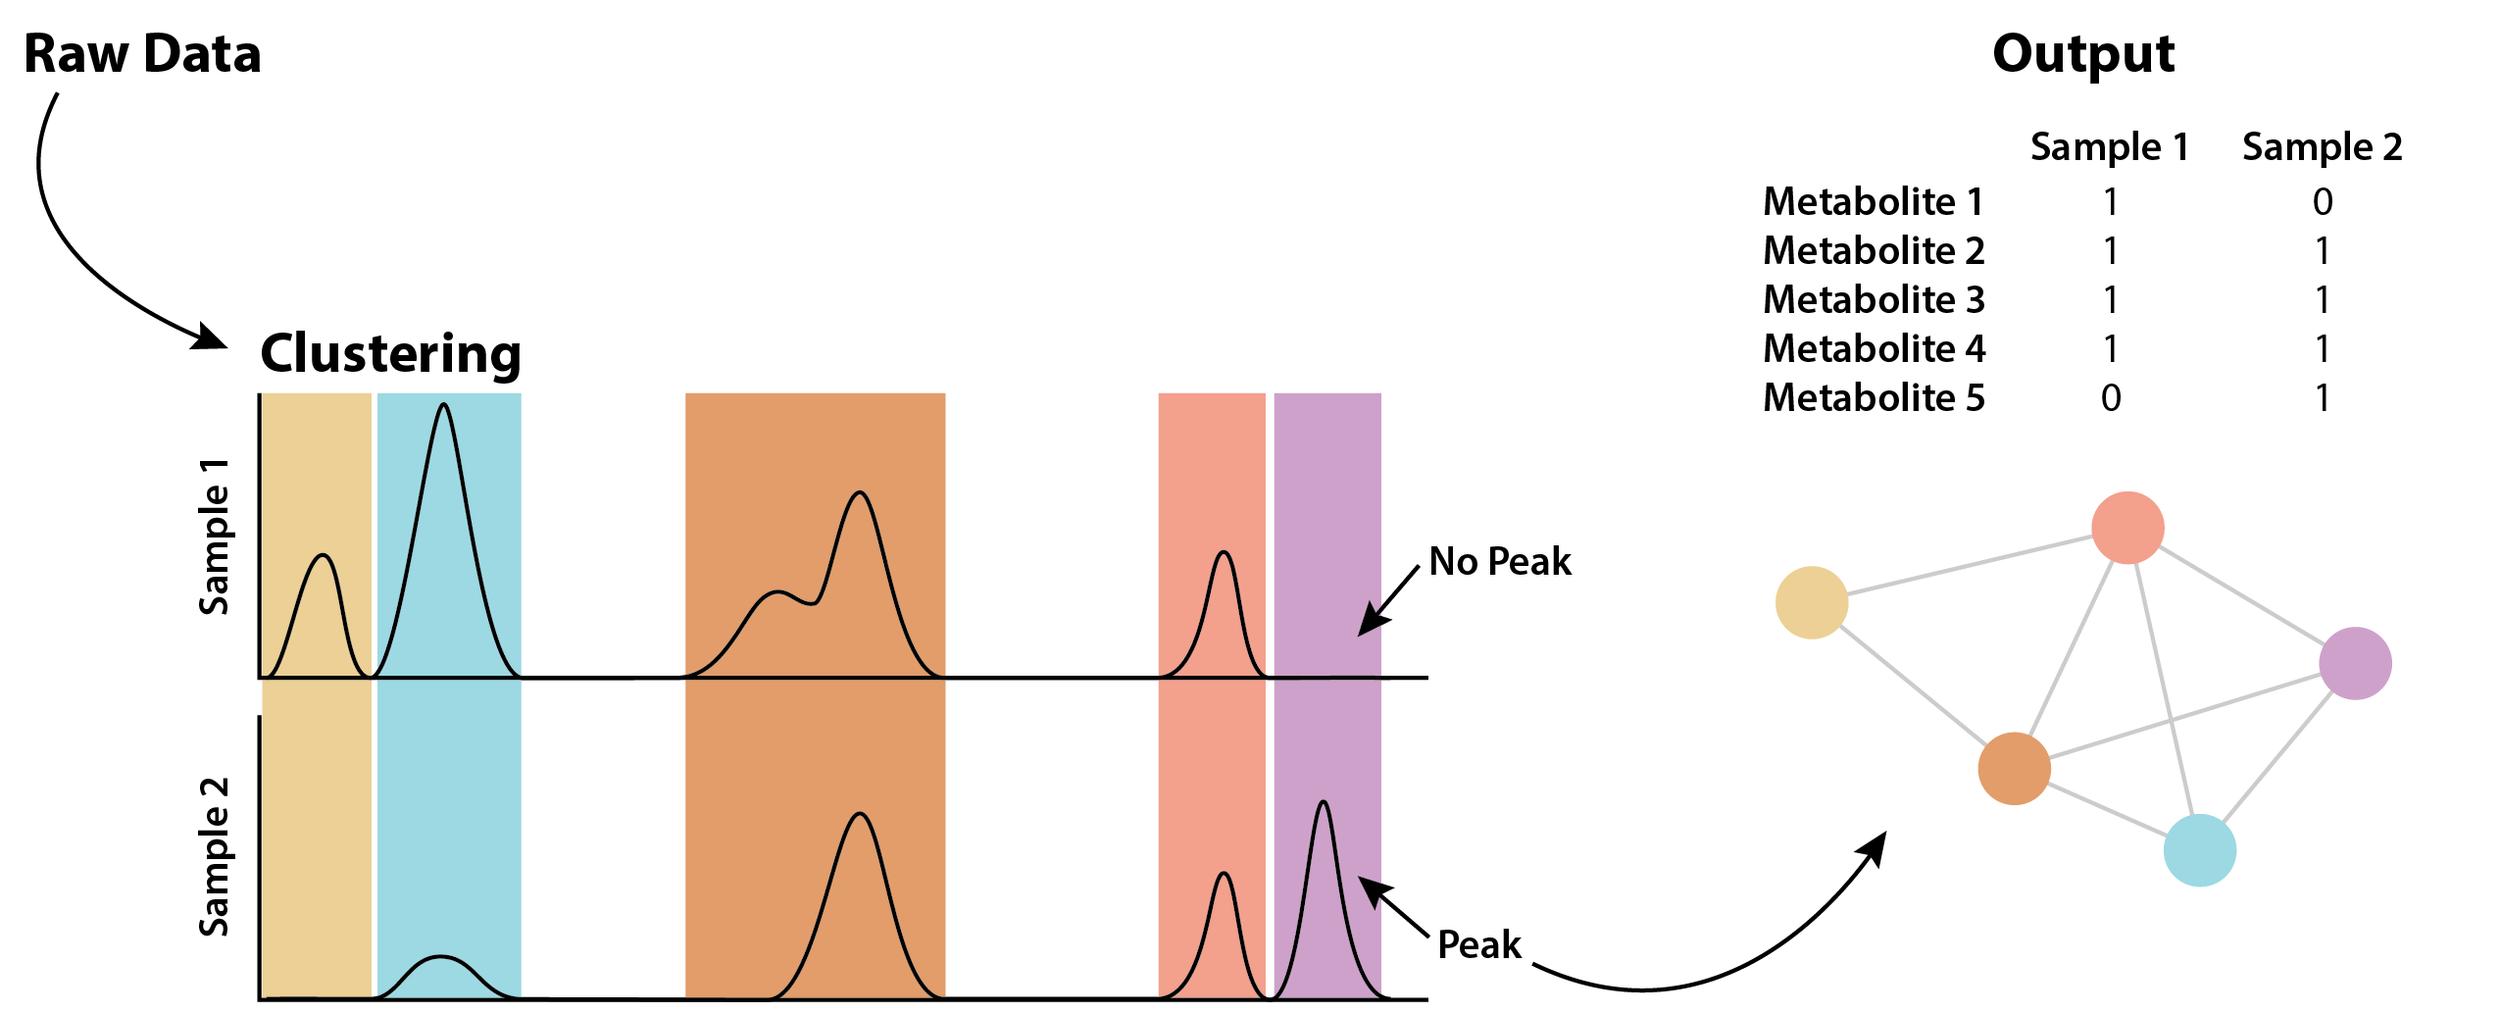
Overview of Classical Molecular Networking
Peak clustering is not straightforward. The goal is to identify the same metabolite in many different samples, but metabolites rarely produce identical spectra. This creates a conundrum. On one hand, stringent clustering will create a separate node for every spectra, losing information on which metabolites are shared and creating an unmanageably large network. On the other hand, loose clustering can incorrectly place different metabolites in the same cluster (node), erasing information crucial to differentiating your samples.
By default, Ometa Flow uses an algorithm called MSCluster, but also offers the option to use Falcon clustering. To learn more about these algorithms, see the publications below.
Traditionally, because classical molecular networking only uses MS2 information, it can only tell you whether a metabolite is present or absent in each sample.* But what if you want to know more about a metabolite than whether it’s just present or absent? This is where FBMN comes in. Instead of using MS2 information to cluster peaks, FBMN performs feature finding before running a molecular network. Feature finding uses MS1 information to identify peaks and measure their peak area, which can give you the relative abundance of a metabolite in each sample (the process of calculating peak area is called peak integration).* Thus, FBMN will not just tell you whether a metabolite is present or absent in a sample, but will also tell you whether it is more or less abundant.

Overview of Feature-Based Molecular Networking
So if FBMN just gives you extra information, why not use it all the time? There are a couple reasons why CMN may be the best choice:
Meta-Analysis: You may have heard that you should never co-analyze samples that weren’t run at the same time on the same instrument. This is because things like retention time and peak shape can vary across instruments and time (especially if you’re messing with things like column and buffer conditions). Feature finding relies heavily on retention time to find peaks. CMN clustering does not. Thus, while FBMN often performs very poorly when analyzing samples across datasets, CMN can be used to perform these types of meta-analyses.**
Manual Tuning: The truth is that feature finding is an art as well as a science. Many feature finding tools exist, most of which rely on different underlying algorithms to find and integrate peaks. The settings you feed into these algorithms can dramatically change your end result. While many of these tools offer default settings that serve as a good starting point, these values should be optimized for each experiment. Even for experts, it can take several rounds of optimization to get good results. Thus, feature finding requires time, effort, and expertise. Ignoring these steps and blindly following default values is a good way to get poor quality outputs.***
There are several popular feature finding algorithms including MZmine, OpenMS, XCMS, MS-Dial, and Metaboscape. Ometa Flow has its own in-house feature finding tool called Everything Bagel and can perform peak integration within classic molecular networking. However, you can also perform feature finding outside of Ometa Flow and upload the results to create a feature-based molecular network.
So which should you use?
As always, it depends on your application. CMN is an excellent choice if you’re just starting out or if you’re performing a large meta-analysis. FBMN is a great choice if you’re good at optimizing parameters and are analyzing single batches of samples.
Personally, I almost always run both.
Here are a couple other considerations when choosing CMN or FBMN:
While the reliance on MS2 information means that CMN is better at meta-analysis, it can also mean that it performs worse on single-batch analyses where information like retention time is genuinely useful. If you know all your samples have similar retention times, then integrating that information through FBMN can lead to more robust results.
Not all feature finding tools are built the same. The best tool for your dataset can depend on things like sample complexity and dataset size, but in general, the best tool for you is the one you understand the best. It’s much better to use a tool where you understand each step and can quality check the outputs than a “better” tool that you use as a black box.
Summary:
| CMN | FBMN | |
|---|---|---|
| Data Preparation | Easy! Just upload your .mzML files and let the algorithm do the work | Requires manual tuning of feature finding parameters*** |
| Meta-analyses | Relies on MS2 information. If your MS2 spectra are similar across experiments, you’re good to go** | Relies on retention time information. Use with caution |
| Output | Presence/absence of metabolites in your samples* | Relative abundance of metabolite in your samples |
*Ometa Flow does offer the option to integrate and report peak areas for samples run through classical molecular networking. This is done using an in-house algorithm whose performance has not been extensively compared to other peak integration tools. You can read more about it here.
**Within reason. CMN uses MS2 information to cluster peaks. MS2 spectra are generally similar in samples run on similar mass spectrometers in the same ion mode. For example, you could cluster metabolites from several datasets run on different QExactives in positive mode.
***Our in house feature finding tool (called Everything Bagel) actually automates this process, but more on that later.
Further Reading
Molecular Networking:
CMN: Wang, M. et al. Sharing and community curation of mass spectrometry data with GNPS. Nat. Biotechnol. 34, 828–837 (2016).
FBMN: Nothias, L. F. et al. Feature-Based Molecular Networking in the GNPS Analysis Environment. Nat. Methods 17, 905–908 (2020).
Clustering:
MSCluster: Frank, A. M. et al. Clustering Millions of Tandem Mass Spectra. J. Proteome Res. 7, 113–122 (2008).
Falcon: Bittremieux, W. et al. Large-scale tandem mass spectrum clustering using fast nearest neighbor searching. RCMS (2021).
Feature finding:
MZmine: Schmid, R. et al. Integrative analysis of multimodal mass spectrometry data in MZmine 3. Nat. Biotechnol. 41, 447–449 (2023).
OpenMS: Röst, H. L. et al. OpenMS: a flexible open-source software platform for mass spectrometry data analysis. Nat. Methods 13, 741–748 (2016).
MS-DIAL: Tsugawa, H. et al. MS-DIAL: Data Independent MS/MS Deconvolution for Comprehensive Metabolome Analysis. Nat. Methods 12, 523 (2015).
XCMS: Tautenhahn, R. et al. XCMS Online: a web-based platform to process untargeted metabolomic data. Anal. Chem. 84, 5035–5039 (2012).
Have more questions? Contact us.